Internship
Vision-language incident retrieval
Text-to-image retrieval of road accidents and vehicle fires from fixed CCTV, trained on a dataset I built from raw footage. Deployed by LTA.
- Recall@5
- >80%
- Recall@10
- >90%
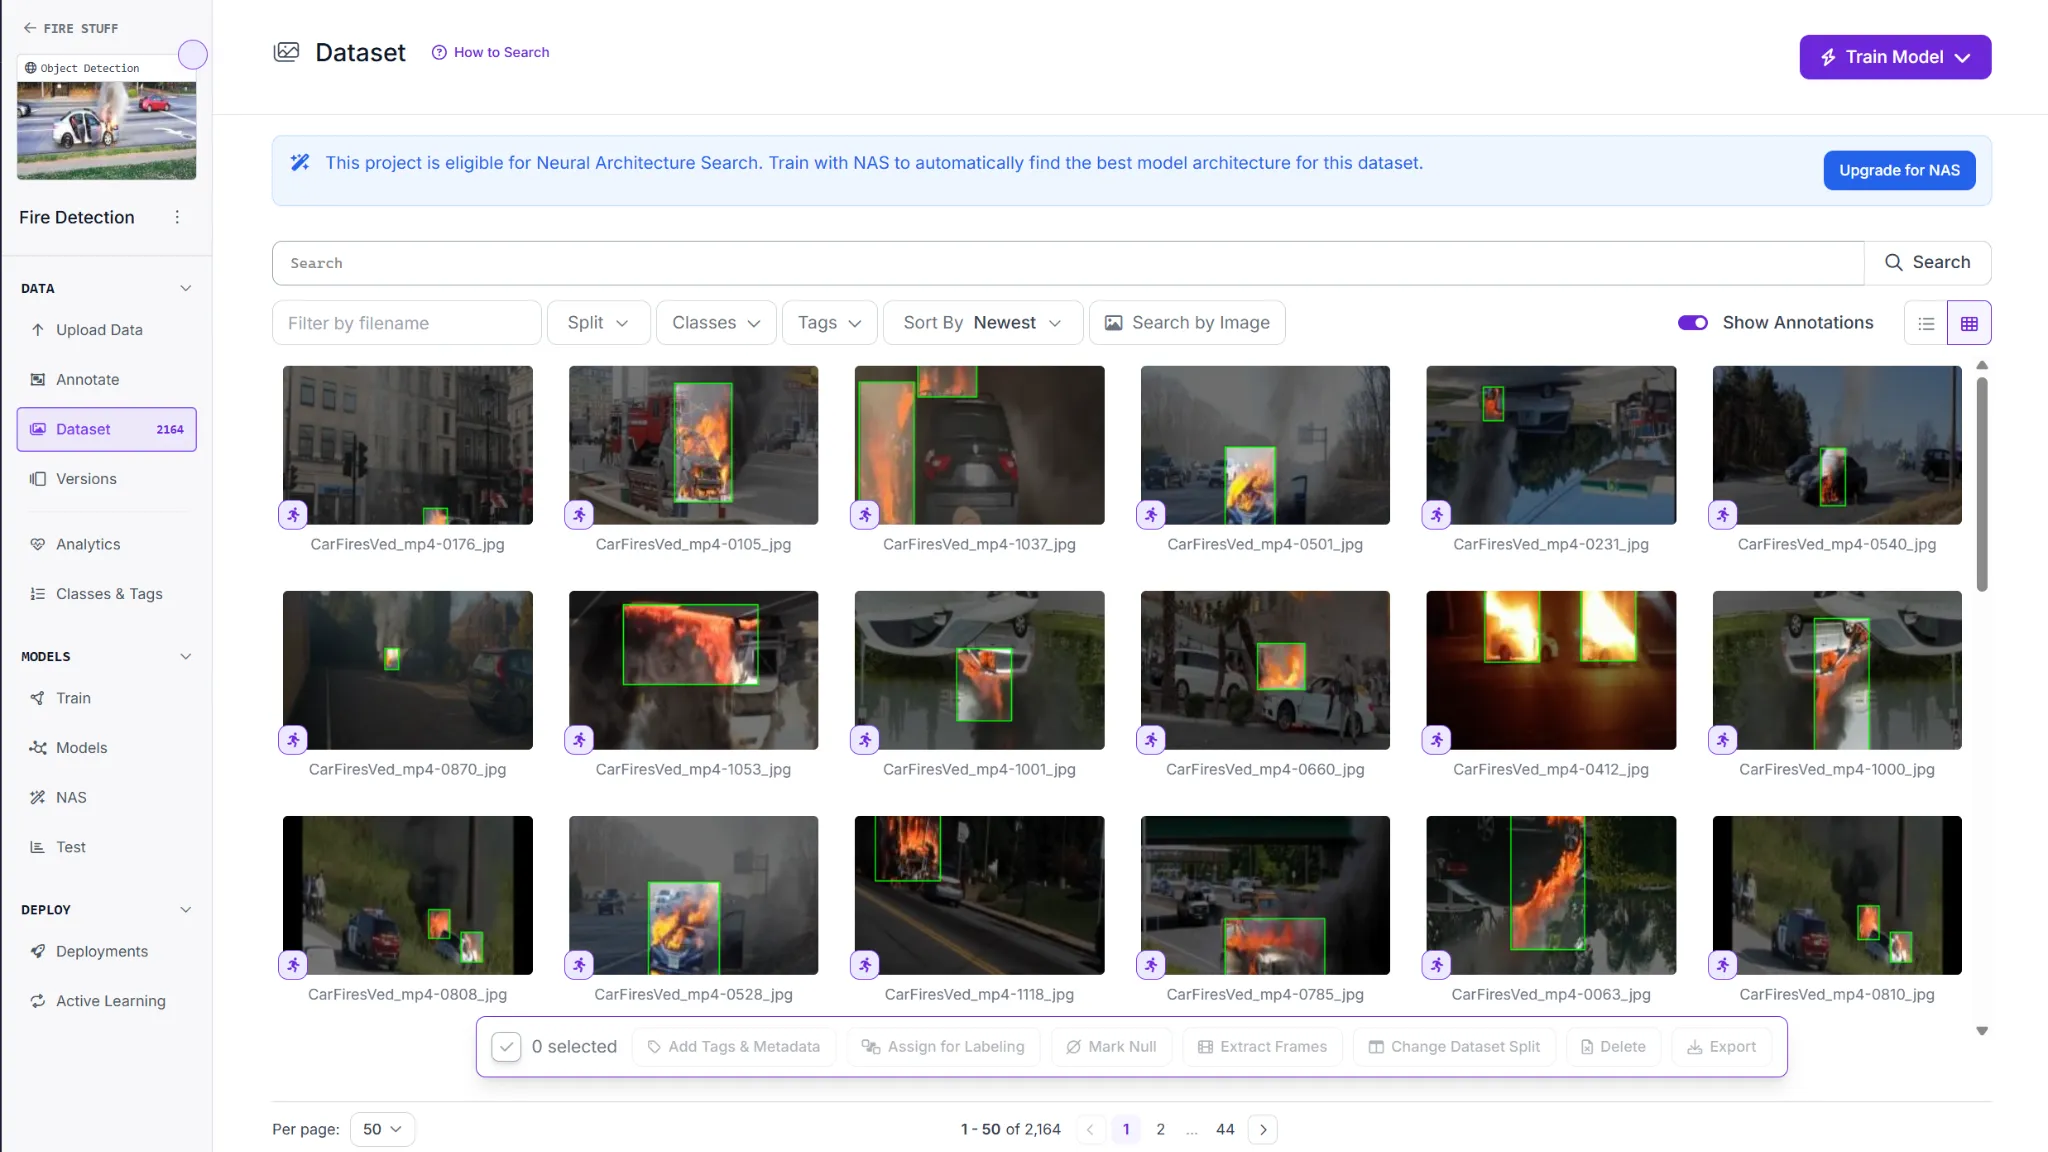
The problem
Identify road accidents and special incidents, such as vehicle fires, from fixed CCTV footage. Real-world incident video is scarce and noisy, so the hard part was turning it into usable training data.
What I built
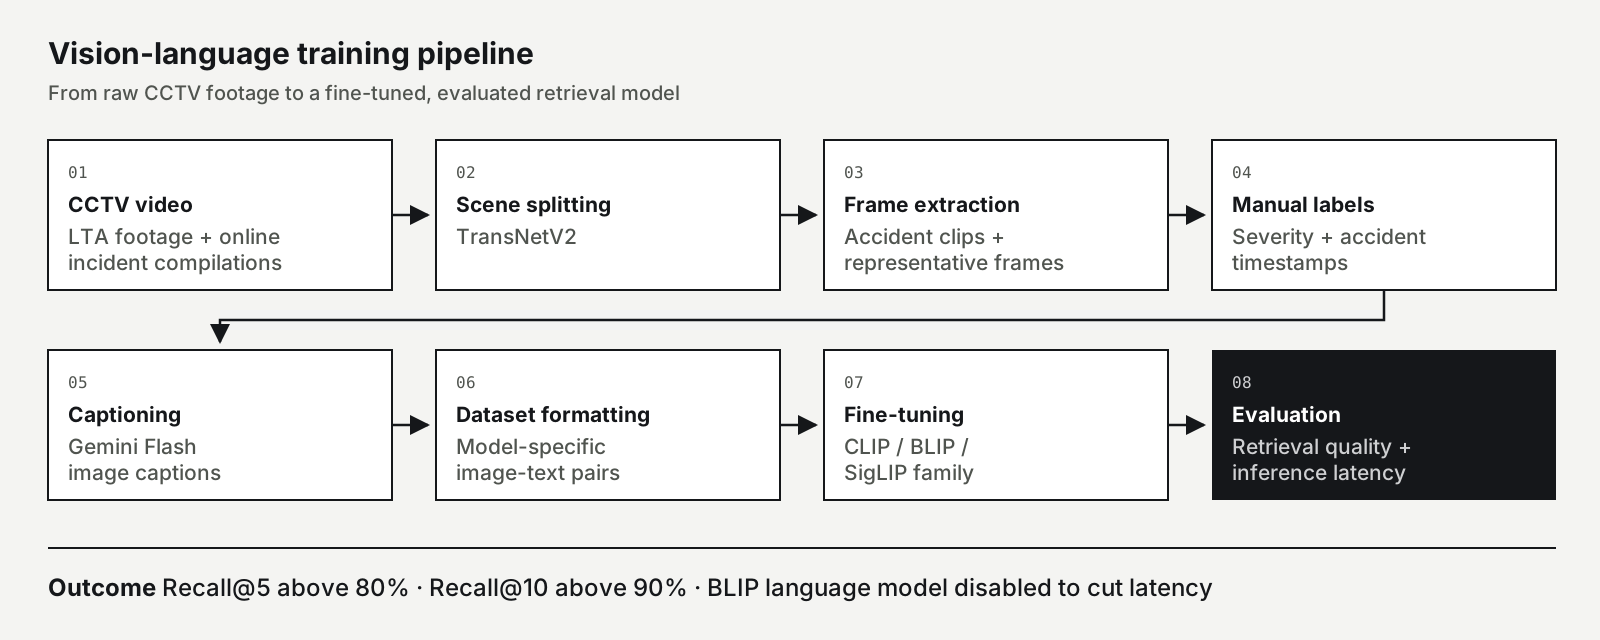
I built the data pipeline end to end, from collection to evaluation:
- Sourced CCTV footage from LTA and from online accident compilations.
- Split videos into scenes with TransNetV2 and extracted frames.
- Built a Streamlit tool for labelling incident severity.
- Marked accident timestamps in Kinovea.
- Auto-captioned frames with Gemini Flash.
- Formatted the datasets and fine-tuned CLIP-, BLIP- and SigLIP-family encoders for text-image retrieval, with Grounding DINO for object detection.
Also at Cynapse: road-marking segmentation with Mask2Former (its own project page), rule-based and shape-based segmentation with traditional CV, and visual re-identification under temporal variation (ResNet-50, OSNet).
Result
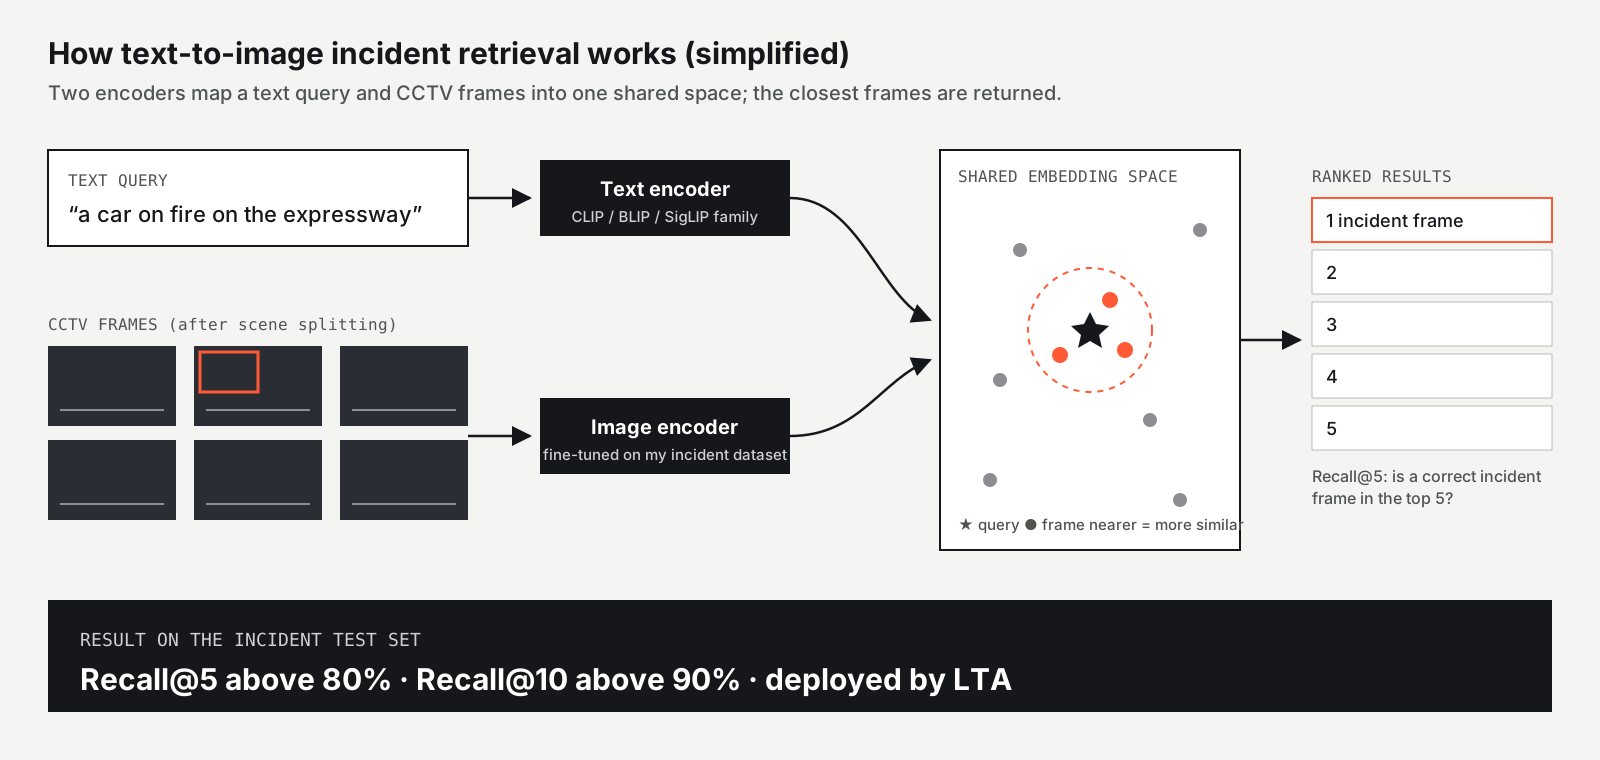
Increasing the vision encoder size lifted retrieval to above 80% Recall@5 and 90% Recall@10. The system is deployed by LTA for traffic incident monitoring.
What I learned
Model performance depends heavily on data quality, preprocessing, evaluation choices and practical inference-speed limits.